I build Rivul AI, a free research workspace (project page). One part of it is paper search: semantic search over metadata for 300 million plus academic papers. The index is built from the OpenAlex snapshot, available as open data (CC0) on the AWS Open Data Registry.
The usual answer at this scale is a distributed vector database. I was curious whether a single machine could serve a read-heavy, rarely updated corpus like this one, with a GPU only for the one-off embedding work. This post covers what worked, what did not, and the numbers I measured.
A quick note on numbers. OpenAlex indexes about half a billion scholarly works. My index covers 300 million plus of them. It leaves out OpenAlex's expansion records, keeps only works with a usable title, and removes older copies of works that appear more than once in the snapshot.
How the system fits together
The design has three parts: a one-off GPU build, an immutable index on disk, and a CPU-only path for live queries. The diagram follows the data from the OpenAlex snapshot to ranked search results.

Table of contents
- 1. Why Single-Stage Retrieval Breaks Down at Scale
- 2. Architecture Overview
- 3. Offline Ingestion: From Snapshot to Index
- 4. Real-Time Search: From Query to Results
- 5. Tech Stack
- 6. Adaptive Ranking: Normalizing Boosts by Score Spread
- 7. Filtering Strategy: Choosing Paths From Measured Costs
- 8. Relevance Floors for Attribute-Based Sorting
- 9. Data Quality: Immutable Index, Read-Time Corrections
- 10. Performance: Measured Latency
- 11. Lessons Learned and What I'd Change
- 12. Resources
1. Why Single-Stage Retrieval Breaks Down at Scale
The embedding model I use, BGE-small (bge-small-en-v1.5), produces 384-dimensional vectors. Each paper record becomes one dense vector, built from its title and abstract (or the title alone when there is no abstract). The index searches that metadata, not the papers’ full text. Stored as float32, one vector takes 1,536 bytes. Multiply that by 300 million plus and the raw vectors alone run to hundreds of gigabytes, before any index or metadata. Comparing every query against all of them is not realistic on one machine.
So the work is split in two. The heavy lifting happens once, offline, when the index is built. Each search then touches only a small slice of that index.
2. Architecture Overview
The diagram at the top of this post shows the whole system. It has three layers:
- Offline ingestion runs once per snapshot. It reads the OpenAlex snapshot, cleans it, embeds every record on a GPU and assembles the index.
- The index on disk is what ingestion produces: about 249 GB of files that never change once published. Corrections live outside it.
- Real-time search runs on one server with 61 GB of RAM and 16 cores. It memory-maps the index and answers each query in five stages.
The next two sections follow the diagram from left to right: first how the index was built, then how a query runs through it.
3. Offline Ingestion: From Snapshot to Index
Before any search could happen, 300 million plus records had to be read, cleaned, embedded and written to disk. Most of the problems here were about memory, disk and time, not retrieval.
Step 1: Read the snapshot
The OpenAlex works snapshot is a set of gzipped JSON Lines files on the AWS Open Data Registry. The builder streams them straight from the bucket and never unpacks them to disk. Eight parser processes read in parallel. The snapshot manifest is pinned at the start and checked again around every shard, so a build can never mix two snapshot versions. If a network stream drops, the reader reopens the file and skips to the first line it has not processed yet, so a blip neither restarts the work nor duplicates records.
Step 2: Clean and de-duplicate
OpenAlex publishes more than 500 million raw work records. A record is kept only if it has a work id and a usable title, and OpenAlex's expansion records are left out. Files are read newest first, so when a work appears more than once, the newest copy wins. Abstracts arrive as an inverted index, a map from each word to its positions, so each one is rebuilt into plain text. The text that gets embedded is the title plus the abstract, cut at 2,000 characters.
Step 3: Embed on the GPU
My first embedding run on CPU managed 17 records per second. At that rate, 300 million plus records would have taken more than 200 days, so embedding moved to a GPU, an NVIDIA H200, separate from the server that answers searches. The model runs in PyTorch through sentence-transformers, in bfloat16, with batches of 8,192 texts sorted by length.
Once the GPU was in place, tokenization became the bottleneck. I moved it into eight CPU processes that keep the GPU fed. Before trusting the faster path, I checked that it produced the same embeddings as the original one, to a cosine similarity of at least 0.999999, on 100K and 1M records. With that change, a full re-embed takes roughly a day of GPU time.
Step 4: Quantize and shard
The GPU worker converts each vector to INT8 as it goes, one byte per dimension, and writes shards of 1 million records. The INT8 scales are calibrated on the first shard and then frozen. Every later shard reports how many values had to be clipped, and the build stops before committing a shard if more than 1% were. Each finished shard is copied to the serving machine and checksummed there, and it only counts as done once its marker file verifies.
Step 5: Assemble the index
On the serving machine, the shards become the index. FAISS trains the IVF-PQ structure on an evenly spaced sample of about 5.2 million vectors. Vectors are then added shard by shard and the parts are merged on disk. The same pass builds the title indexes and the compressed metadata blocks. Every file is checksummed, and the new index only becomes live when all checks pass. The result is about 249 GB, of which about 121 GB is the INT8 vectors.
Working within 61 GB of RAM
Almost every choice above came from fitting inside one machine:
| Constraint | What would have broken | What I did |
|---|---|---|
| Memory while embedding | Holding a large shard of float32 vectors in RAM | 1M-record shards, at most two float32 chunks alive at once, written through memory-mapped temp files |
| Memory for de-duplication | A Python set of hundreds of millions of ids | A sorted int64 array, about 2.7 GB, merged in batches |
| Memory for FAISS training | Training IVF-PQ on every vector | An evenly spaced sample of about 5.2 million vectors, then adding vectors shard by shard and merging on disk |
| Memory for the title-prefix index | About 2.2 billion entries, because each title is indexed under its first 3, 4, and up to 12 words; one global sort would need about 44 GB | 256 buckets sorted one at a time, each under 1 GB |
| Disk | Early plans for a richer layout needed 600 to 800 GB | Compact metadata in compressed 256-row blocks; the final index is about 249 GB, of which about 121 GB is INT8 vectors |
| Time | A multi-day run restarting from zero after any failure | A marker file written last for every shard, settings pinned for the whole run, and resume from the last good shard |
What went wrong along the way
- The GPU run was interrupted. The first run used very large 50M-record shards. When the GPU instance stopped mid-run, everything after the last finished shard was lost. I restarted with 1M-record shards and a marker for each one, so a stop now costs at most one shard.
- A slow pass that looked fine on small data. The first title-prefix pass read records through the normal fetch path at 180 records per second, which would have taken weeks. Reading the compressed blocks directly measured 21,712 records per second, bringing the full pass to about four hours.
4. Real-Time Search: From Query to Results
With the index built, each search moves from the query input through five processing stages on one server. The times below are for one new query, measured on the live index.
- Query
- Embed
- Find candidates
- Re-score
- Add title matches
- Rank
1. Embed the query (10 ms)
The query is embedded with the same BGE-small model, on CPU, using the instruction prefix the model recommends for retrieval queries: "Represent this sentence for searching relevant passages:".
2. Find candidates (17 ms)
FAISS returns about 1,000 candidates from the IVF-PQ index. IVF splits the vector space into lists around learned centroids and scans only the lists nearest the query. PQ compresses each vector into a 32-byte code: 32 sub-quantisers of 8 bits each. On a 1M-record test corpus, scanning more lists raised mean Recall@20 from 0.91 to 0.97 at 1,000 candidates, with very little extra search time.
3. Re-score the candidates (122 ms)
PQ codes are good for finding candidates but too coarse to order them. So the 1,000 candidates are re-scored against the INT8 copy of their vectors. Each dimension has its own symmetric scale, giving up to 127 quantization levels on either side of zero. Only the candidates are dequantised before cosine similarity is computed. This is the slowest stage for a new query because it reads those vectors from disk; once they are in memory it takes under 1 ms.
4. Look up titles (21 ms)
Vector search is weak at something people do all the time: pasting the exact title of a paper. At full scale, the query "Attention Is All You Need" fell outside the top 1,000 semantic candidates. So titles are also looked up directly, in an exact-title index and a title-prefix index. Matches are added to the candidate pool and scored the same way. An exact title match gets a large boost. A query that matches the start of a title pulls in up to 50 works, with a smaller, bounded boost, so a paper that is semantically much closer can still win.
5. Rank (70 ms)
The final order combines similarity with citations and recency. Citations are log-scaled and saturate at 100,000; recency adds a small boost that grows with the publication year. How much these boosts count depends on the query, which the section on score spread explains. Metadata for the page is read here, with the read-time corrections applied.
Try Search papers on rivul.ai
5. Tech Stack
Most of the system is Python. Index construction is a batch job that uses temporary GPU capacity; live search runs on one CPU server. There is no managed vector database.
| Layer | Implementation |
|---|---|
| Source data | OpenAlex works snapshot (CC0), streamed from the AWS Open Data Registry as gzipped JSON Lines with boto3 |
| Parsing and metadata | Eight Python worker processes, NumPy memory-mapped files, and metadata stored in zlib-compressed 256-row blocks |
| Tokenization | Hugging Face fast tokenizer running in eight CPU processes that keep the embedding GPU fed |
| Embedding | BAAI/bge-small-en-v1.5 through PyTorch and Sentence Transformers: 384-dimensional vectors, bfloat16 inference, NVIDIA H200 |
| Vector storage | Per-dimension INT8 vectors for cosine re-scoring, plus 32-byte product-quantization codes for candidate retrieval |
| Candidate retrieval | FAISS on CPU: IVF-PQ with 131,072 lists, an HNSW coarse quantizer, and memory-mapped inverted lists |
| Title retrieval | Separate exact-title and title-prefix indexes recover papers that semantic retrieval misses |
| Final ranking | INT8 cosine similarity combined with bounded title, citation, and recency boosts normalized by each query’s score spread |
| Serving | FastAPI and Uvicorn on one 16-core server with 61 GB of RAM; query embedding runs on CPU |
- IVF
- Partitions vectors into lists so each query searches only nearby regions.
- PQ
- Compresses each vector into a short code for fast approximate comparison.
- HNSW coarse quantizer
- Finds the IVF lists nearest the query without comparing every centroid.
- Recall@20
- The share of the exact top 20 neighbors recovered by the approximate search.
6. Adaptive Ranking: Normalizing Boosts by Score Spread
This one surprised me. Some queries have candidates packed within 0.02 cosine of each other. Others spread across 0.2. A fixed citation weight means something very different in each case. In a tight cluster it overwhelms similarity. In a wide one it barely registers.
It matters at this scale because thousands of works cluster around any concept. Without some weight on citations, a preprint with no citations can outrank a landmark paper on a 0.03 similarity edge. With too much weight, famous papers crowd out the right answer.
So the boosts are scaled by the spread of each query's candidate scores. The weights are set at a reference spread of 0.10: 0.15 for citations and 0.03 for recency. A query's actual spread scales them, clamped between 0.25 and 2 times. A tight query and a wide query now get the same relative pull.
7. Filtering Strategy: Choosing Paths From Measured Costs
Filters look simple: a year range, a minimum citation count, open access, a topic or a field. At this scale they are not. If you filter a fixed candidate list after the fact, a selective filter leaves almost nothing. In one test, asking for 8 times the usual candidates with a filter that matched 0.04% of the corpus left 3 usable candidates out of 8,000.
So I measured the two options instead of guessing:
| Operation | Measured cost |
|---|---|
| Ask FAISS for 1,000 candidates | about 11 ms |
| Ask FAISS for 64,000 candidates | about 20 ms |
| Ask FAISS for 256,000 candidates | about 56 ms |
| Score eligible rows one by one | about 100 µs per row |
Asking for more candidates is nearly flat in cost. Walking eligible rows by hand grows steadily. That gave three paths:
- A filter that matches at most 10,000 rows is scored exactly, row by row.
- Otherwise the candidate request is scaled by how rare the eligible rows are, from 8 times up to 512 times.
- If the page is still thin because the matching rows sit in other parts of the vector space, the search probes more lists, once.
8. Relevance Floors for Attribute-Based Sorting
Sorting by most cited, newest or oldest showed a different problem. The candidate pool always holds some loosely related works. Sort a title search by citations, and a famous but unrelated paper that merely landed in the pool jumps to the top.
So attribute sorts only order rows whose similarity is within half of the candidate score spread from the best match. Exact title matches always stay in. Weaker matches are left out rather than appended at the end, where they would restart the order part-way down the list.
9. Data Quality: Immutable Index, Read-Time Corrections
The built index never changes. Rebuilding it takes a long time, so I wanted a way to correct individual records without touching it.
Any scholarly corpus of 300 million plus records that merges many upstream sources, such as DOIs, publisher deposits and record merges, will have some messy entries. That is the nature of data at this size. The categories I ran into:
- A record whose publication year did not match when it started being cited.
- A citation count that looked implausible for the paper shown.
- A landmark paper whose conference version was missing from the snapshot I built from.
Two small files handle these at read time.
Overrides patch the display fields of a named work. Identity and the normalised title used for exact lookup cannot be changed, so a correction can never redirect one work to another. Corrected values are used for ranking, sorting and filtering too. Citation counts are never replaced, because there is no verified replacement value. A doubtful count is flagged instead: ranking and citation filters treat that work as uncited, while the card still shows the published number.
Supplements add up to 500 hand-verified records for works missing from the snapshot. They are embedded at startup with the same query model and merged at query time. A supplement record joins semantic results only when it scores at least as well as the weakest candidate the index returned, so it appears only where it would have been retrieved anyway.
Every entry records the sources it was checked against and when. Fixes like these can also be reported back to OpenAlex, so they help everyone who uses the data.
10. Performance: Measured Latency
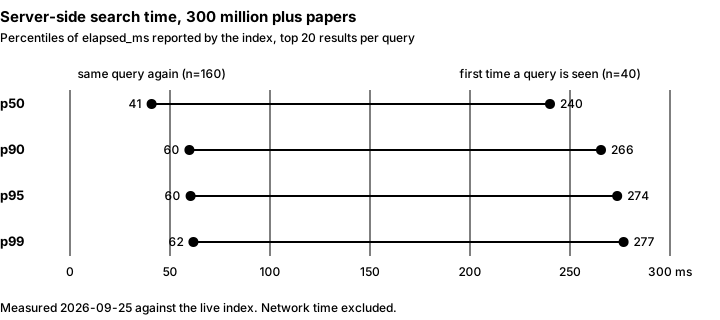
On 2026-09-25 I timed the live index using the search time it reports for each request, top 20 results per query. That excludes the round trip over the internet. Two cases behave very differently: a query the index has not seen recently, and the same query again.
The largest change is the INT8 re-score: reading candidate vectors costs 122 ms for a new query and under 1 ms once those pages are cached.
A new query took a median of 240 ms, with a p99 of 277 ms. Repeating a query brought the median down to 41 ms. The stage times in the pipeline diagram above show where the difference comes from: on a repeat, the INT8 re-score drops from 122 ms to under 1 ms and ranking from 70 ms to about 20 ms.
Most of the gap is disk reads: the re-score has to fetch about 1,000 stored vectors, and once those pages are in memory it barely costs anything. So the honest summary is about 240 ms for a new query and about 40 ms for a warm one.
Filters and the newest sort ask for 2,000 candidates instead of 1,000, which is why they sit near 60 ms warm instead of 40. These are some of the queries I timed, with the top result exactly as the index returned it:
How the latency and recall measurements were taken
- Latency is server-side search time for the top 20 results; internet round-trip time is excluded.
- The cold distribution uses 40 queries not seen recently. The repeated-query distribution uses 160 runs.
- The serving machine has 16 CPU cores, 61 GB of RAM and a fast NVMe drive.
- Recall@20 covers the semantic path before title matching or citation and recency boosts.
- The full-scale exact baseline scans the INT8 vectors; each build was tested with five queries.
| Query | Sort and filter | Median (20 runs) | Top result as returned |
|---|---|---|---|
| speculative decoding large language models | Relevance | 40 ms | Unlocking Efficiency in Large Language Model Inference: A Comprehensive Survey of Speculative Decoding (2024) |
| retrieval augmented generation | Most cited | 40 ms | RAGAs: Automated Evaluation of Retrieval Augmented Generation (2024) |
| coastal wetlands blue carbon storage | Relevance, year ≥ 2020 | 58 ms | All tidal wetlands are blue carbon ecosystems (2024) |
| CRISPR base editing off-target effects | Relevance, open access only | 58 ms | Off-target effects in CRISPR/Cas9 gene editing (2023) |
| protein structure prediction | Newest | 60 ms | Protein structure prediction (2026) |
| 4-bit quantization of LLM weights | Relevance | 40 ms | LLM-FP4: 4-Bit Floating-Point Quantized Transformers (2023) |
Recall at full scale
Speed is only half of it. At each build size I measured Recall@20 for the semantic path alone: the top 20 after IVF-PQ candidates and INT8 re-scoring, compared with the top 20 from an exact scan of every vector, before any title matching or citation and recency boosts. At full scale the exact scan runs over the INT8 vectors, because a float32 copy of everything is too large to keep. Each build was tested with only 5 queries against a 0.95 target for the mean, so treat these numbers as a preliminary diagnostic, not a reliable quality estimate.
| Index size | Builds tested | Mean Recall@20 | Worst query |
|---|---|---|---|
| 10K records | 3 | 1.00 | 1.00 |
| 1M records | 2 | 0.97, 0.99 | 0.95 |
| Full corpus (300 million plus) | 1 | 0.90 | 0.65 |
Recall held at 0.97 to 0.99 on 1M records, then fell to a mean of 0.90 on the full corpus, below the 0.95 I had set as my own target. The worst of the five test queries returned 13 of the true top 20. Because the full-scale baseline is itself an exact scan of the INT8 vectors, that loss comes from the candidate stage, whose settings I tuned at 1M records. INT8 on its own is close to float32: re-scored cosine similarity matched it at 0.99996. All of it runs on one machine with a fast NVMe drive.
11. Lessons Learned and What I'd Change
- Design for updates earlier. I built the index as an immutable snapshot first and treated updates as later work. Adding and removing records without a rebuild is the harder problem, and I would plan for it from the start.
- Re-tune at full scale sooner. I grew the index in stages, from 10K records up to the full corpus, with quality checks at each step. Small samples can flatter compression, and some search settings tuned at 1M records were carried to the full corpus. I would measure them again at full size earlier.
- Keep two kinds of benchmark from day one. Natural-language queries and exact-title lookups fail in different ways. I measure them separately, and one blended average would have hidden both problems.
- Build the correction path before launch. Read-time overrides and supplements turned out to be one of the most useful parts of the system.
12. Resources
- openalex-semantic-search on GitHub, the open-source code behind this post (Apache 2.0)
- Rivul AI, free for every account
- Rivul AI project page
- How Search papers works
- OpenAlex, the open dataset behind the index
- OpenAlex snapshot on the AWS Open Data Registry